Fog Map
Compare interpretations of a spec and rank the decisions that need clarification.
- Role
- Solo, AI-assisted prototype session
- Stack
Problem
Small ambiguities in a spec can produce incompatible data models, APIs and behavior. A ranked comparison makes those decisions visible before implementation.
What I built
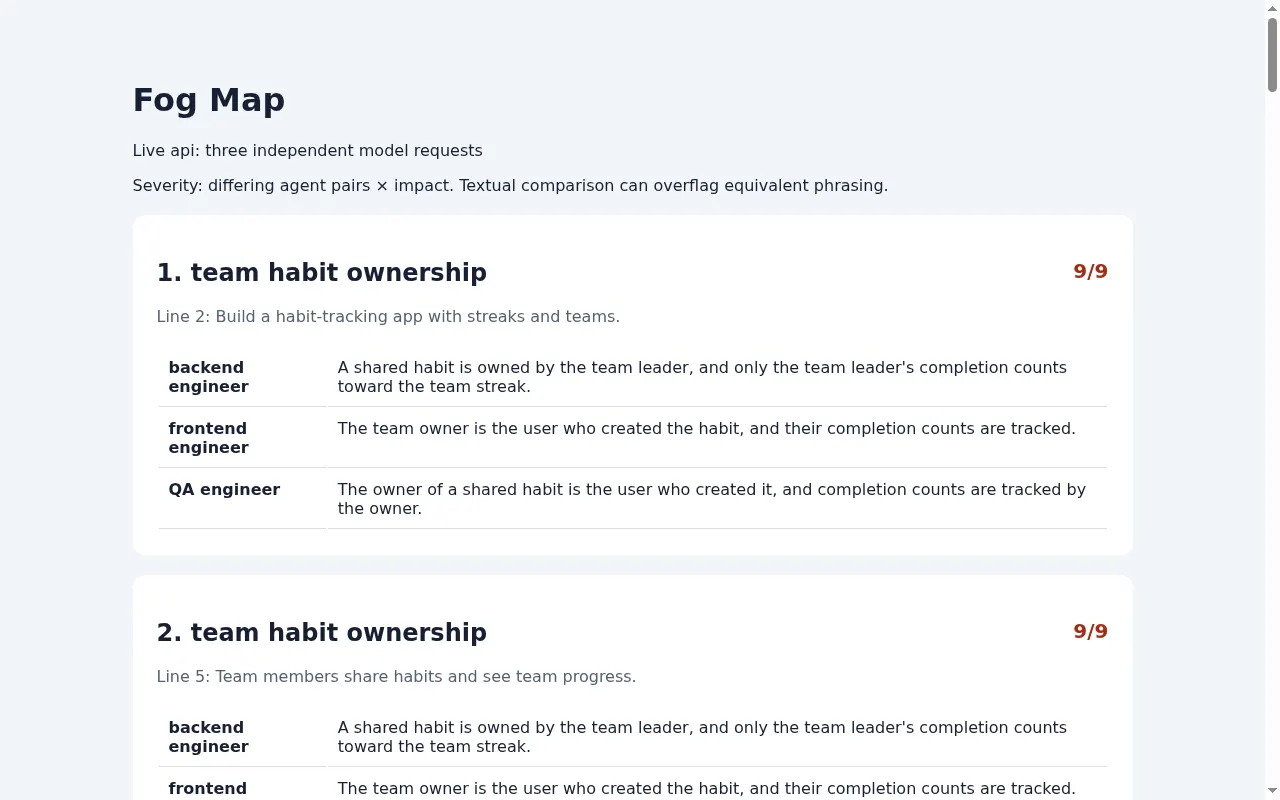
An AI-assisted prototype makes three independent model calls with backend, frontend and QA personas, preserving data models, endpoint sketches and line-attributed implementation assumptions.
The CLI groups decisions by source line and topic and exports ranked HTML, Markdown and JSON evidence. Severity combines disagreement and impact. Live Ollama and API adapters are implemented.
Results
- Three real Qwen3 1.7B Q4 CPU calls produce six ranked line/topic findings across five topics, including concrete conflicts over day boundaries, grace policies, historical edits and notification timing. Total usage: 2,876 tokens (1,444 input and 1,432 output).
- Five tests pass, including provider evidence capture, attribution, scoring and HTML escaping. Earlier failed small-model and interrupted runtime attempts are retained. The comparison is textual; the live result is a sample demonstration, not an accuracy estimate on arbitrary specifications.
- The GitHub Pages exhibit displays the recorded model run with downloadable evidence; new model analyses remain a local CLI operation.